b8c.io Build faster. Ship smarter. Scale infinitely.

b8c.io

Build faster. Ship smarter. Scale infinitely.

Latest Articles

Blameless Doesn't Mean Toothless: What Incident Reviews Look Like When They Actually Work
Product & Delivery

Blameless Doesn't Mean Toothless: What Incident Reviews Look Like When They Actually Work

The blameless postmortem was supposed to create psychological safety and drive real learning. For a lot of teams, it's become a ritual where everyone agrees nothing was anyone's fault and the same incidents keep happening. Here's what goes wrong—and what a genuinely useful incident review actually requires.
Git Log Is a Crystal Ball: Reading Engineering Health Between the Commits
Engineering Strategy

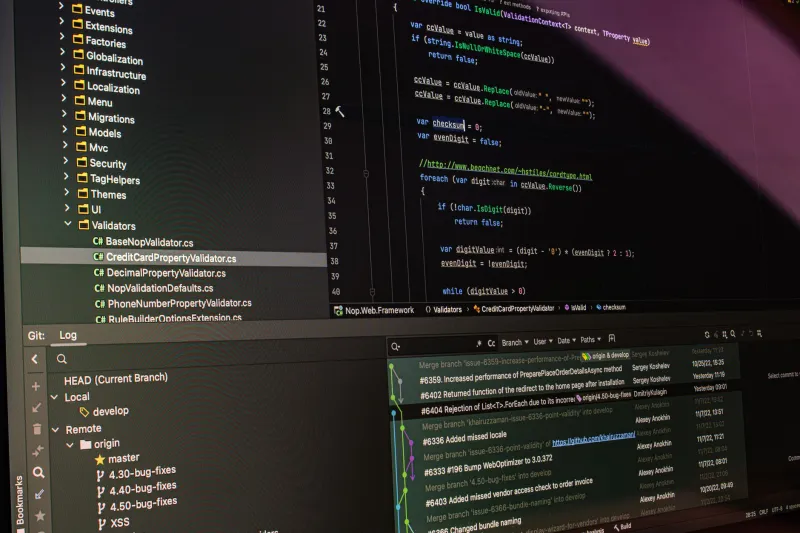
Git Log Is a Crystal Ball: Reading Engineering Health Between the Commits

Your commit history isn't just a changelog—it's an unfiltered record of how your team actually works, where your architecture is failing, and who's quietly burning out. Most orgs treat git as a backup system. The ones that don't use it to catch problems months before they explode.

The Dependency You Didn't Write Is the One That'll Break You
Engineering Strategy

The Dependency You Didn't Write Is the One That'll Break You

Modern apps ship with hundreds of dependencies nobody fully audited, maintained by people nobody knows, pulling in sub-dependencies nobody asked for. Automated scanners give you a false sense of control. The real supply chain risk isn't the CVE that gets patched—it's everything that doesn't.

API Docs That Lie: The Documentation Drift Problem Quietly Wrecking Developer Trust
Product & Delivery

API Docs That Lie: The Documentation Drift Problem Quietly Wrecking Developer Trust

The moment your API ships, the clock starts ticking on how long your docs stay accurate. Most teams treat documentation as a delivery artifact rather than a living contract, and the resulting drift creates a cascading trust problem that slows down every developer who touches your platform.

Your Logs Are Lying by Omission: The Context Gap That Turns Debugging Into Archaeology
Engineering Strategy

Your Logs Are Lying by Omission: The Context Gap That Turns Debugging Into Archaeology

Volume isn't the problem with most logging setups — context is. Teams generate millions of log lines per hour and still can't answer basic questions about what a user experienced or why a transaction failed. The gap between logging a lot and logging usefully is where incidents become all-nighters.

The Kill Switch You Never Tested: Why Your Rollback Plan Is a Bedtime Story You Tell Yourself
Engineering Strategy

The Kill Switch You Never Tested: Why Your Rollback Plan Is a Bedtime Story You Tell Yourself

Feature flags feel like a safety net until you actually need one at 2am and discover the net has holes. Most teams haven't tested their rollback path under real load, and when a broken feature starts melting production, the escape hatch they counted on turns into a trap door.

Ninety Percent Coverage, Zero Percent Confidence: The Test Suite Illusion Costing You in Production
Engineering Strategy

Ninety Percent Coverage, Zero Percent Confidence: The Test Suite Illusion Costing You in Production

Your CI/CD pipeline goes green, the coverage badge says 91%, and your team ships with confidence. Then production blows up in a way your tests never even imagined. Here's why coverage numbers are often the most expensive lie in your entire stack.

Twelve Repos, Four Languages, One Bug: The Hidden Velocity Tax of Distributed Systems Debugging
Product & Delivery

Twelve Repos, Four Languages, One Bug: The Hidden Velocity Tax of Distributed Systems Debugging

The pitch for microservices was independence — teams moving fast, deploying freely, scaling what matters. What a lot of teams got instead was a debugging experience that requires six browser tabs, three Slack threads, and an org chart just to trace a single failing request. Here's what the cognitive overhead is actually costing you, and what you can do about it without blowing up your architecture.

Terraform Applied. Reality Diverged. Your Infrastructure Code Isn't the Source of Truth Anymore.
Engineering Strategy

Terraform Applied. Reality Diverged. Your Infrastructure Code Isn't the Source of Truth Anymore.

You checked in the Terraform. You ran the plan. You felt good about it. But somewhere between the last apply and today, your actual infrastructure quietly stopped matching what's in version control — and nobody noticed until it mattered. IaC drift is more common than teams admit, and the false confidence it creates is its own kind of technical debt.

The Friday Deploy Myth: If You're Scared to Ship at 4pm, Your Safety Net Has Holes
Engineering Strategy

The Friday Deploy Myth: If You're Scared to Ship at 4pm, Your Safety Net Has Holes

Avoiding Friday deploys isn't a best practice—it's a symptom. Teams with solid rollback mechanisms, feature flags, and real observability don't care what day it is when they ship. The 'no deploy Friday' rule is just risk management for teams that haven't built the infrastructure to manage risk properly.

The Invisible Tax on Your Engineering Team: Why Fragmented Work Is Killing Real Output
Product & Delivery

The Invisible Tax on Your Engineering Team: Why Fragmented Work Is Killing Real Output

Your developers aren't slow—they're constantly interrupted. Between tool-hopping, review queues, on-call rotations, and Slack pings, the average engineer gets maybe three hours of real focus time per day. That's the throughput problem nobody's tracking on your sprint board.

Nobody Actually Ran the Playbook: The Incident Readiness Gap Hiding in Your Wiki
Engineering Strategy

Nobody Actually Ran the Playbook: The Incident Readiness Gap Hiding in Your Wiki

Your incident response documentation looks great in Confluence. But when the pager goes off at 2am, that wiki page won't save you—muscle memory will. Most teams find out their runbooks are fiction only when a real outage proves it.

Your Third-Party Code Is Someone Else's Backdoor
Engineering Strategy

Your Third-Party Code Is Someone Else's Backdoor

That npm install you ran six months ago didn't just pull in one package — it pulled in dozens you've never heard of, maintained by people you've never vetted. Dependency risk isn't about the libraries you know. It's about the ones you've completely forgotten.

You Chose Every Cloud. Now You're Drowning in All of Them.
Engineering Strategy

You Chose Every Cloud. Now You're Drowning in All of Them.

Multi-cloud was supposed to be the smart play — no vendor lock-in, maximum flexibility, negotiating leverage. Instead, most teams end up with fragmented tooling, doubled operational overhead, and an infrastructure that no single engineer fully understands. Here's why defensive diversification often costs more than the risk it was designed to prevent.

Drowning in Data: How Your Observability Stack Became the Incident It Was Supposed to Prevent
Engineering Strategy

Drowning in Data: How Your Observability Stack Became the Incident It Was Supposed to Prevent

More logs don't mean more clarity — they often mean slower response times, higher bills, and engineers too exhausted by alert noise to catch what actually matters. Here's why your observability investment might be working against you, and what to do about it.

Dead Letters Don't Lie: What Your Message Queue Is Hiding From You
Engineering Strategy

Dead Letters Don't Lie: What Your Message Queue Is Hiding From You

Your message queue feels reliable until you realize half your events died quietly three days ago and nobody noticed. Silent async failures don't just lose data — they corrupt it, slowly and systematically. Here's how to stop treating your queue like a black box and start treating it like the critical infrastructure it actually is.

When Governance Became the Bottleneck: Breaking Free from Approval Theater
Engineering Strategy

When Governance Became the Bottleneck: Breaking Free from Approval Theater

Every security review, compliance gate, and sign-off workflow you added had a reason behind it. The problem is those reasons may have expired years ago, while the friction they create is very much still alive. Here's how to tell the difference between governance that actually protects you and governance that just makes everyone feel better about doing nothing.

Your Postmortem Is a Press Release, Not a Plan
Engineering Strategy

Your Postmortem Is a Press Release, Not a Plan

Teams write postmortems to feel like they've done something. But polished documents with tidy timelines and carefully neutral language aren't the same as actually fixing the system that broke. Here's why most incident reviews fail before the follow-up ticket is even closed.

The Release Ritual: How Your Deployment Process Became a Three-Day Prayer Circle
Engineering Strategy

The Release Ritual: How Your Deployment Process Became a Three-Day Prayer Circle

Somewhere between writing the code and getting it live, your team invented a bureaucracy. What should take minutes now takes days — and most of the gates you're jumping through aren't protecting anyone. Here's how to figure out which checkpoints actually matter.

Scared to Ship: How Fear-Driven Deployment Culture Is Quietly Strangling Your Team
Engineering Strategy

Scared to Ship: How Fear-Driven Deployment Culture Is Quietly Strangling Your Team

Your team isn't slow because of bad code — they're slow because deploying feels like defusing a bomb. When fear replaces confidence in your deployment process, every release becomes a ritual of anxiety instead of a routine act of engineering.